Scale Your IT & AI Infrastructure with Zenix Pods

Deploy dedicated, top 1% senior engineering pods that architect generative AI systems, high-scale Kubernetes clouds, and resilient microservices in predictable 14-day agile sprints.

Velocity
14-Day Sprints
Expertise
Top 1% Senior
IP Ownership
100% Client Repos
Zenix AI Senior Engineering Pod

Enterprise IT & Generative AI Services

Engineered for extreme performance, banking-grade security, and rapid ROI.

AI
Applied AI & LLMs

Generative AI & Agent Systems

Enterprise RAG search architectures, fine-tuned domain models, autonomous multimodal agents, and zero-leakage enterprise security.

  • ✓ Sub-50ms Vector Search on 10M+ Tokens
  • ✓ Enterprise PII Redaction & Guardrails
  • ✓ Multimodal Vision & OCR Pipelines
SRE
Cloud & DevOps

Cloud Architecture & Kubernetes

Self-healing cloud infrastructure, Terraform IaC, automated GitOps CI/CD pipelines, and FinOps infrastructure cost optimization.

  • ✓ AWS / GCP / Azure Kubernetes
  • ✓ Zero-Downtime Blue/Green Deployment
  • ✓ 24/7 Datadog & Prometheus Metrics
API
Platforms & Mesh

High-Scale Microservices

Distributed backend systems engineered in Go, Node.js, and React, Kafka event streams, and sub-100ms API response rates.

  • ✓ gRPC & Event Stream Integration
  • ✓ High-Throughput GraphQL / REST APIs
  • ✓ SOC2 & ISO 27001 Security Perimeters
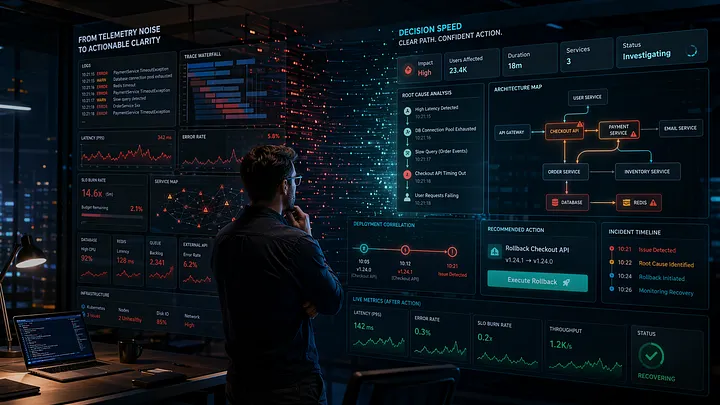
Telemetry Mesh

Autonomous Cloud & Observability Mesh

Every deployment features continuous OpenTelemetry distributed tracing, AI latency monitors, and proactive error prediction dashboards.

● Prometheus ● OpenTelemetry ● Grafana
Zenix AI Cloud Observability Telemetry

Enterprise Infrastructure Matrix

The 4-stage pipeline deployed in every Zenix AI production engagement.

STAGE 01 11.4 ms
Ingestion Layer

Hybrid Vector RAG

Sub-50ms hybrid dense embeddings across 10M+ indexed documents.

STAGE 02 142 ms
Intelligence Core

Enterprise LLM Mesh

Dynamic model routing with semantic caching reducing API costs.

STAGE 03 98k req/sec
Execution Mesh

Kubernetes SRE Pods

Autoscaling microservices connected via ultra-low latency gRPC.

STAGE 04 SOC2 Pass
Perimeter

Zero-Trust Edge IAM

mTLS mutual authentication, continuous SAST/DAST, and audit trails.

The 14-Day Agile Delivery Model

From architectural design to live production cutover in structured milestones.

Zenix 14-Day Sprint Roadmap
01

Discovery & Architecture Blueprint (Days 1-3)

Threat modeling, schema design, latency targets, and fixed sprint commitments.

02

Rapid Core Prototyping (Days 4-7)

Working build in staging with automated unit test suites and direct client repo access.

03

Production Hardening & QA (Days 8-11)

Load tests, vulnerability scans, latency optimization, and disaster recovery simulation.

04

Deployment & 24/7 SLA Handover (Days 12-14)

Live production cutover with 24/7 telemetry monitoring and comprehensive engineering documentation.

Why CTOs Choose Zenix AI

Release Velocity
6-9 Month Waterfall Releases
14-Day Working Sprint Cycles
Engineering Seniority
Junior Staffing Model
Top 1% Senior Staff & AI Architects
Code & IP Ownership
Vendor Lock-In & Black-Box Repos
100% Direct Client Repo Ownership

Frequently Asked Questions

Everything you need to know about our engineering standards and SLAs.

How fast can a Zenix engineering pod onboard to our codebase? ↓

Our pods are pre-vetted and typically begin sprint execution within 5 to 7 business days following architecture alignment and NDA execution.

Do we maintain 100% intellectual property ownership of the code? ↓

Yes. All source code, documentation, Terraform scripts, and fine-tuned model weights belong exclusively to your company from day one.

How do you guarantee enterprise production security? ↓

We operate under strict SOC2 and ISO 27001 standards with zero-data-retention enterprise LLM agreements, automated vulnerability scans, and encrypted IAM perimeters.

Ready to Build Your Next-Generation IT Infrastructure?

Partner with senior engineers and AI architects to accelerate your next enterprise technology initiative.